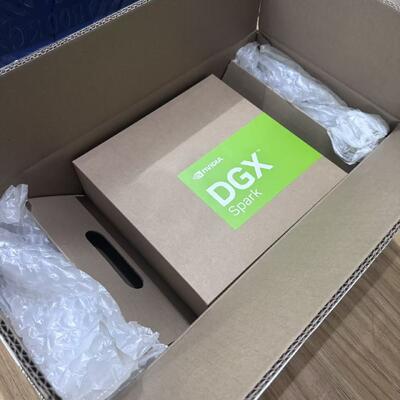
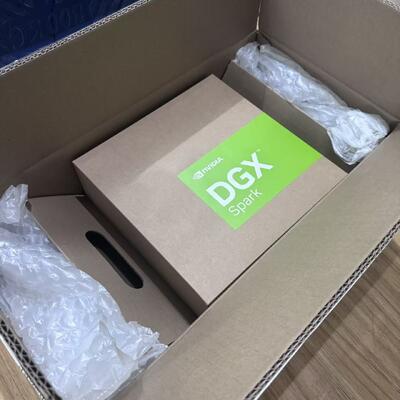
NVIDIA DGX Spark — 128GB Unified Memory AI Workstation
The NVIDIA DGX Spark brings data-centre class AI computing to a desk. Built around the GB10 Grace Blackwell Superchip, this AI Workstation delivers up to 1 PFLOPS of FP4 compute with 128GB of unified coherent memory, so a single compact unit can load models that normally need a multi-GPU server. The 128GB unified memory pool is shared directly between the Grace CPU and the Blackwell GPU, which removes the copy overhead that slows down conventional PCIe systems when a large model exceeds GPU memory.
Because the machine runs the same NVIDIA AI software stack used in DGX Cloud and HGX systems, prototypes built locally move to a data-centre deployment without re-writing code. Developers typically use one unit for local LLM inference and fine-tuning, then link two units over the built-in ConnectX-7 200Gb/s ports to work with larger models and longer context windows.
Technical Specifications
| Model | NVIDIA DGX Spark |
| Superchip | GB10 Grace Blackwell |
| AI Performance | 1 PFLOPS FP4 (sparse) |
| GPU Architecture | NVIDIA Blackwell |
| CPU | 20-core Arm (10 Cortex-X925 + 10 Cortex-A725) |
| Memory | 128GB LPDDR5x unified coherent memory |
| Storage | 4TB NVMe M.2 SSD |
| Networking | ConnectX-7 Smart NIC, 2 x QSFP 200Gb/s, 10GbE RJ-45 |
| Wireless | Wi-Fi 7, Bluetooth 5.3 |
| Software | NVIDIA DGX OS, CUDA, TensorRT, NIM and NGC catalogue |
| Model Scale | Up to 200B parameters single unit, 405B with two linked |
| Ports | 4 x USB-C, HDMI 2.1a, 10GbE RJ-45, 2 x QSFP |
| Power | 240W external power adapter |
| Dimensions | 150 x 150 x 50.5 mm, approx. 1.2 kg |
Where This AI Workstation Is Used
- Local LLM inference and fine-tuning — run quantised 70B-class models or fine-tune mid-size models on a desk, with proprietary data never leaving the office.
- Prototype then scale — the same DGX software environment means a working prototype can be lifted to DGX Cloud or HGX servers with minimal code changes.
- Edge and field AI — a 240W desktop footprint fits labs, clinics, factory floors and vehicles where a rack cannot be installed.
- Agentic and RAG development — 128GB unified memory holds the model, vector index and retrieval pipeline at the same time, which shortens test cycles.
- Two-unit clusters — ConnectX-7 QSFP ports link two machines to reach 405B-parameter scale for research teams.
- Education and research — departments can teach CUDA, NIM microservices and model optimisation without booking shared GPU time.
Questions Buyers Ask
Q: What does 1 PFLOPS FP4 mean in practice?
It is the peak Blackwell tensor throughput at FP4 precision with sparsity, the format used by most inference engines today. For day-to-day work, the more useful figure is the 128GB memory ceiling, because it decides which models will load at all.
Q: Which models can run on 128GB unified memory?
A single unit comfortably handles models up to roughly 200B parameters at reduced precision, including quantised Llama, Mistral and Qwen variants. Linking two units over QSFP extends capacity to about 405B parameters.
Q: Can this AI Workstation replace a GPU server?
For development, fine-tuning and single-user inference, yes — it runs the same CUDA and TensorRT stack. For multi-tenant production serving with dozens of concurrent users, a rack-mounted accelerator server is still the right tier.
Q: Is the operating system locked to DGX OS?
DGX OS is the validated Ubuntu-based image with drivers, CUDA and NVIDIA container runtime pre-installed. It is the supported path, and it keeps parity with DGX Cloud images.
Q: How is the unit checked before shipment?
Each unit is powered on, the DGX OS image version is recorded, GPU, memory and NVMe health are read out, and both QSFP ports are verified for link. Buyers receive the test log and serial number before dispatch.
Tell us the model size, framework and deployment timeline you are targeting, and we will confirm DGX Spark configuration, accessories and lead time before the order is packed.

 Your message must be between 20-3,000 characters!
 English